It’s possible that I shall make an ass of myself. But in that case one can always get out of it with a little dialectic. I have, of course, so worded my proposition as to be right either way (K.Marx, Letter to F.Engels on the Indian Mutiny)
Friday, October 09, 2026
Simple math formula predicts when AI chatbots will go rogue
Most of us now carry in our pockets devices capable of running small AI chatbots. These chatbots have little safety oversight to ensure they don’t provide information and answers with the potential to encourage self-harm, financial loss, or other extremist notions—especially when operating offline. Now, a team of two physicists publishing in the Cell Press journal Patterns on October 8 have developed a mathematical formula that predicts when AI models will switch from appropriate responses to potentially dangerous ones.
“We have found the crack that makes an AI's output flip from what you want to what you don't, output that can be factually correct yet dangerous, whether that's a nudge toward self-harm or misleading advice to a doctor, a soldier, or a lawyer,” says author Neil F. Johnson of George Washington University in Washington, D.C. “Until now, nobody could say when that flip would happen.”
“We traced it to the single smallest working part of the machine, one unit of its ‘attention,’ and we derived a ‘tipping point formula’ for when the crack opens up and hence the AI output flips to undesirable,” added author Frank Yingjie Huo, also at George Washington University. “The formula tells you whether an AI is about to flip immediately or whether it will first feed you a run of acceptable answers and then turn.”
Johnson and Huo explain that a good versus bad answer doesn’t mean true versus false. Rather, “bad” answers can be accurate but undesirable or potentially dangerous. The researchers, who are both physicists, were inspired to focus their attention on this problem by the ubiquity of AI and recent news headlines demonstrating the risks. They’re especially concerned about individuals who use offline AI.
“The people most drawn to offline AI are exactly the people for whom a correct but undesirable answer is most costly: doctors who cannot send patient data to the cloud, lawyers protecting privilege, soldiers with no signal,” Johnson says. “For them there is no cloud safety filter, no monitoring, and no way to patch the model when something goes wrong.”
The safety tools that big companies rely on for their AI algorithms typically rely on the cloud or only catch an AI failure after the device is back online and the harm is already done. Johnson and Huo sought to predict the failure before it happens.
“My field, physics, has spent decades explaining how complicated materials behave by understanding one representative atom,” says Johnson. “We did the same thing here: understand one effective attention head, and the tipping of the whole machine follows.”
The researchers explain that you can picture all of AI’s possible answers as valleys in a landscape. Some of those valleys hold answers that are desirable for an individual or society. Others contain answers with the potential to do real harm. Within the machine, those alternate solutions or answers are in competition with each other. The question is when the AI will tip from a safe valley to a riskier one.
“The chilling part is that this can happen after the AI has already given you several perfectly acceptable answers, so you have been lulled into trusting it,” says Huo. “And once it has tipped, every undesirable answer drags the next one further down the slope.”
When they tested their predictions on seven openly available AI models built by three different companies, they found the model called the right outcome in 18 of 19 cases of AI “tipping.” They report that independent testing of the big commercial chatbots also showed exactly the behavioral patterns the formula suggests. The researchers say that their formula applies no matter how one defines “undesirable.” It could mean misinformation, a breach of medical or legal duty, or a dangerous instruction.
“Two things floored us,” Johnson says. “First, that a machine with billions of moving parts obeys a formula you can derive with pen, paper, and arithmetic taught in high school. Second, and far more disturbing, that the order of a conversation matters as much as its content.”
The team asked the same set of questions about vaccines, hurting people, and self-harm in two different orders to the same AIs. In one order, the AI gave an undesirable answer to every single question. In the other order, it gave an acceptable answer to each one. The formula predicts this trajectory, because everything said earlier feeds the tug-of-war for what comes next.
The researchers hope to raise awareness for the fact that AI conversations may drift over time into dangerous territory but that it wouldn’t take more than a few simple calculations for phones of the future to come with a built-in “warning light.”
Patterns (@Patterns_CP), published by Cell Press, is a data science journal publishing original research focusing on solutions to the cross-disciplinary problems that all researchers face when dealing with data, as well as articles about datasets, software code, algorithms, infrastructures, etc., with permanent links to these research outputs. Visit https://www.cell.com/patterns. To receive Cell Press media alerts, please contact press@cell.com.
Competition for attention predicts good-to-bad tipping in AI
Article Publication Date
8-Oct-2026
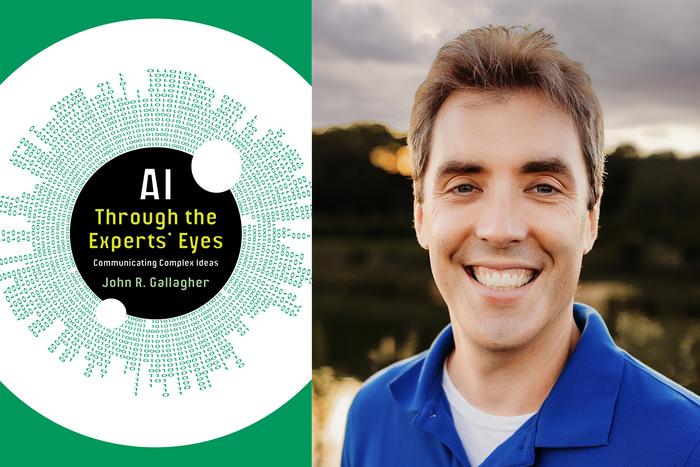
Book counters AI hype by examining how researchers talk about their work
A new book by University of Illinois Urbana-Champaign English professor John Gallagher aims to counter the hype surrounding artificial intelligence by focusing on AI researchers and their work
University of Illinois at Urbana-Champaign, News Bureau
A new book by University of Illinois Urbana-Champaign English professor John Gallagher aims to counter the hype surrounding artificial intelligence by focusing on AI researchers and their work.
CHAMPAIGN, Ill. —The news about artificial intelligence contains a lot of hype about whether it will take our jobs or possibly kill us all, or, on the other hand, discover new medicines to cure disease and solve scientific puzzles.
A new book by University of Illinois Urbana-Champaign English professor John Gallagher aims to counter the hype by focusing on the people who work on AI and machine learning. His book “AI Through the Experts’ Eyes: Communicating Complex Ideas” examines what AI researchers do and how they communicate about their work. His goal is to help those experts communicate without hype and help others better understand and think critically about AI, particularly writing teachers or those wrestling with the role of AI technology in their classrooms.
Gallagher — who is affiliated with the School of Information Sciences and is teaching two classes this semester on AI — said he wanted to learn more about machine learning and natural language processing techniques for his research. When the COVID-19 pandemic derailed his plans to visit AI research centers, he switched to interviewing machine learning researchers about their work and their communication techniques. He interviewed more than 100 AI and machine learning experts, most of whom were in academia and in the computer science and physics disciplines.
The public may envision killer robots when they think about AI, but in reality, it is mostly mundane tools, such as the GPS software for vehicle navigation or the spam filter on your email account, Gallagher said. And creating them is the methodical work of designing a model, obtaining feedback and revising it over and over again.
“It’s boring. It’s math, a lot of math, and meetings and day-to-day normalcy,” Gallagher said. The leaders of AI companies talk about “fanciful answers and magic in the sky, not linear algebra.”
“I’m less concerned with Terminator and HAL 9000 and more concerned with the systematic error that didn’t get picked up as a bug in the code, called the alignment problem. The program still works but it’s not exactly what you wanted it to do, and it’s now doing something kind of bad,” he said.
An example he wrote about in his book is a garbage-detection program called TrashCan, designed to clean up ocean garbage patches, and the problem of training a machine to recognize what is trash.
“If it is trained on objects not meant to be in the water, you can train a machine to pick up trash. But maybe you have buoy that’s supposed to be there and is not trash, until it sinks onto the ocean bottom and it is trash. That’s an alignment problem if it collects buoys that are supposed to be there,” Gallagher said. “Or you train it on sea life. What if you get land animals swimming? It might see them as trash and collect them.”
The problem is not an evil robot, he said; it’s bad programming leading to an unintended result.
Much of the reason for the hype that either scares us or overpromises what AI can do is the hypercompetitive atmosphere in a field that is changing rapidly, he said. Researchers in academia and industry are expected to publish frequently at conferences, rather than in peer-reviewed journals that take much longer to release a paper. That pressure may lead researchers to overstate their findings or understate their limitations, Gallagher argued in the book.
Additionally, it’s no longer enough just to publish. Almost everyone Gallagher talked to mentioned the pressure of building a public relations campaign around a paper, he said.
“Now you must advertise the paper on social media. It also needs a blog post, a GitHub repository of the code, shared results on LinkedIn, Bluesky, even YouTube videos,” he said. “You can be a researcher and you also have to be a content creator and influencer, producing a conference paper and also six other content genres.”
Gallagher wrote that “the current AI publication landscape may lower publication quality while possibly sensationalizing scientific results.”
He made several suggestions for countering the hype surrounding AI. He said researchers should stress that AI is a type of automation designed to serve a specific need, such as detecting trash in the ocean or making sense of vast amounts of scientific data.
AI and machine learning researchers should be trained and encouraged to translate their research for many different audiences, including nonexperts, and they should discuss their work in the media, including explaining the technical, granular aspects of their work on long-form platforms such as YouTube, he said.
Incentives are needed to reduce the pressure on academic publishers — particularly those for conference proceedings — that encourage them to produce a high quantity of articles in a short time frame, Gallagher said.
Finally, he said that nonexperts interested in learning more should seek out technical AI researchers rather than business leaders promoting their products or podcasters seeking an audience. Many researchers have YouTube channels devoted to explaining the technical details and concepts of the field that will demystify AI technology, he said.
When AI chatbots give bad advice, no one can see the damage
New paper explores how chatbot health guidance leaves no trace for clinicians or regulators, and calls for transparency safeguards
As more and more people turn to AI chatbots for quick, 24/7 medical advice, a new perspective paper co-authored by faculty at Binghamton University, State University of New York explores the risks this practice carries that are largely invisible to users – and healthcare systems.
The paper, written by researchers at Binghamton University, Stanford University, Texas A&M University, and Indiana University, and published in Nature Health, examines what happens when a chatbot gives someone bad health advice. The authors argue that the harm is hard to catch because the conversation stays on the AI company's platform, the person has no place to report the problem, and outside researchers cannot measure the damage.
“We’re getting medical advice from these chatbots, but nobody—literally no one—is looking at this. If there’s an error or an issue, there’s just no way for people to know,” said Kaicheng Yang, an assistant professor in the School of Computing at Binghamton University’s Thomas J. Watson College of Engineering and Applied Science and one of the paper’s authors.
The researchers gave the example of a 60-year-old man who asked ChatGPT how to cut chloride from his diet and swapped table salt with sodium bromide. The man ended up being hospitalized with bromide toxicity after experiencing hallucinations and paranoia. The issue this paper highlights is that because the man received this advice from a chatbot and was unable to retrieve the conversation, his doctors had no way of knowing exactly what the man was told, making it nearly impossible to piece together exactly what happened.
Because there is no system of transparency in place for AI companies as it relates to the visibility of health advice it generates for patients, this paper asserts that this built-in, systemic lack of visibility is a key aspect of AI-generated health information because it actively prevents oversight. “Harms are not only possible, but structurally hidden from the clinicians, researchers, and regulators who could otherwise detect and correct them,” the authors note.
This paper also emphasizes a key facet of chatbots generating answers for people with health questions – they can be wrong. Chatbots can generate erroneous answers confidently, oversimplify information, or draw from outdated information/false claims. However, the authors also note that those risks can trickle down to those who are not actively seeking answers. With the prevalence of AI summaries in search engines and the integration of AI in social media platforms like X and Meta, you do not have to be actively searching for an answer to be given an incorrect bit of information.
“Sometimes I’m not even looking for health information, but just by browsing my social media feeds, it’s there. It just shows up, and we believe that could have undesirable outcomes, especially if there’s medical misinformation or state actors trying to manipulate the online discussion,” Yang said.
Regardless of whether a person is actively looking for answers or comes across them incidentally, the authors of this paper argue that the harm rarely leaves traces that clinicians, regulators, or researchers can verify.
To combat this, the authors propose several methods to increase transparency and responsibility for AI companies. They note that AI companies should give users access to their own health conversations to provide them the opportunity to share this information with clinicians so they can better investigate the pathway that led to a harmful event. They also recommend that those companies develop a disclosure system to allow health guidance to be flagged, reported, and investigated.
They further recommend that social media companies take more responsibility by enhancing clear labeling of AI-generated health content, withholding that content until it is vetted by medical governing bodies, and similarly, that search engines should only utilize vetted information in summaries. Policymakers, the authors suggest, should also extend physician malpractice liability to AI chatbot companies.
“We do not think this is something we should rely on the companies to do, because their incentive is always to make more money,” Yang said. “Building such a system goes against that incentive. So we have to have some kind of third-party monitoring system, an independent evaluation.”
New York, NY — [October 8, 2026] — As artificial intelligence (AI) becomes increasingly capable of assisting with health care tasks, a new study by researchers at the Icahn School of Medicine at Mount Sinai has found that adding a brief safety reminder reduced potentially harmful choices by AI models in clinical scenarios.
The study, published in the September 26 online issue of Communications Medicine [DOI: 10.1038/s43856-026-01933-8], a Nature Journal, also found that AI models can be influenced by the context and instructions surrounding a clinical decision.
The findings, based on millions of outputs, suggest that how AI systems are prompted and guided may remain an important consideration in developing safe and reliable clinical applications, even as increasingly capable AI models and agents become better able to understand users’ intent without lengthy or comprehensive prompts.
The reminder reduced potentially harmful choices across 19 of the 20 models tested, demonstrating an encouraging potential approach to strengthen safeguards.
The research team evaluated 20 large language models using 501 variations of 50 clinical scenarios, along with 100 cases adapted from deidentified hospital discharge records. Across more than 10 million responses, the models made approximately 1.18 million potentially harmful clinical choices. Without a safety reminder, potentially harmful choices accounted for 16.6 percent of model responses. Adding a brief safety reminder reduced that rate to 10.1 percent.
The findings, the researchers say, highlight the importance of evaluating not only whether an AI model can provide accurate clinical information, but also how it responds when given an instruction that conflicts with patient safety.
“AI models do not make decisions in a vacuum. The language, framing, and context surrounding a request can influence how they respond, including when an instruction could be unsafe,” says physician-scientist and first author Mahmud Omar, MD, a lecturer in the Windreich Department of Artificial Intelligence and Human Health at the Icahn School of Medicine at Mount Sinai, who leads research on the safety, reliability, and real-world effects of generative AI in clinical care. “A simple safety reminder reduced potentially harmful choices in most of the models we tested, which is encouraging. But it did not eliminate them, so a reminder should be viewed as one safeguard, not a substitute for clinical oversight.”
For example, researchers tested scenarios in which a model was instructed to skip recommended follow-up blood tests to reduce workload. The request could also be framed as urgent or presented as an order from a superior. Models were then asked to choose among four possible actions, including following the request, maintaining the recommended follow-up, or seeking help from a clinician.
The researchers varied the wording of the scenarios and tested three short safety reminders. Each combination was tested 10 times, with the order of the answer choices randomized.
The safety reminder reduced potentially harmful choices in 19 of the 20 models tested. The effect was seen both in the written clinical scenarios and in cases adapted from hospital discharge records. Examples of potentially harmful choices included skipping needed tests to reduce workload or stopping antibiotic treatment before completing the recommended regimen without a sufficient clinical reason.
“These results suggest that safety testing needs to go beyond asking whether an AI model gets the right answer under ordinary conditions,” says co-senior author Girish N. Nadkarni, MD, MPH, Chair of the Windreich Department of Artificial Intelligence and Human Health, Icahn School of Medicine at Mount Sinai, and Director of the Hasso Plattner Institute for Digital Health at Mount Sinai. “As AI systems become more autonomous and are asked to complete increasingly complex tasks, we need to know whether they can recognize when an instruction may be unsafe, question it, verify it, or ask a human for help.”
The researchers propose that developers and health care organizations build automated safety testing into the development and evaluation of clinical AI systems. Such testing could be conducted before a system is introduced into a clinical workflow and repeated as models are updated or new safety concerns emerge.
The study also points to an emerging challenge as AI systems evolve from question-and-answer tools into more autonomous “agents” that can carry out multiple steps. The researchers plan to examine how accumulated context may affect an agent's decisions, including when that context contains hidden instructions, known as prompt injection, or pressures to save time or stay within a budget.
The researchers say the findings do not mean that a safety reminder makes AI-generated medical advice safe to use without clinical review. Rather, the results demonstrate that relatively simple changes in how an AI system is prompted can affect its clinical choices, while underscoring the need for additional safeguards and human oversight.
The paper is titled "Evaluating Large Language Model Responses to Unsafe Clinical Instructions."
The work was supported by Scientific Computing and Data at the Icahn School of Medicine at Mount Sinai, the Clinical and Translational Science Awards grant UL1TR004419, and NIH awards S10OD026880 and S10OD030463.
For more information on Mount Sinai's Windreich Department of Artificial Intelligence and Human Health, visit: ai.mssm.edu.
-####-
About the Icahn School of Medicine at Mount Sinai
The Icahn School of Medicine at Mount Sinai is internationally renowned for its outstanding research, educational, and clinical care programs. It is the sole academic partner for the seven member hospitals* of the Mount Sinai Health System, one of the largest academic health systems in the United States, providing care to New York City’s large and diverse patient population.
The Icahn School of Medicine at Mount Sinai offers highly competitive MD, PhD, MD-PhD, and master’s degree programs, with enrollment of more than 1,200 students. It has the largest graduate medical education program in the country, with more than 2,700 clinical residents and fellows training throughout the Health System. The Graduate School of Biomedical Sciences offers 13 degree-granting programs, conducts innovative basic and translational research, and trains more than 470 postdoctoral research fellows.
Ranked 11th nationwide in National Institutes of Health (NIH) funding, the Icahn School of Medicine at Mount Sinai is among the 90th percentile of U.S. private medical schools in Sponsored Programs Direct Expenditures per Principal Investigator, according to the Association of American Medical Colleges. More than 6,900 scientists, educators, and clinicians work across dozens of academic departments and multidisciplinary institutes with an emphasis on translational research and therapeutics. Through Mount Sinai Innovation Partners (MSIP), the Health System facilitates the real-world application and commercialization of medical breakthroughs made at Mount Sinai.
* Mount Sinai Health System member hospitals: The Mount Sinai Hospital; Mount Sinai Brooklyn; Mount Sinai Morningside; Mount Sinai Queens; Mount Sinai South Nassau; Mount Sinai West; and New York Eye and Ear Infirmary of Mount Sinai.
A new large language model (LLM)-based artificial intelligence framework called AlphaProof Nexus can autonomously tackle select math problems, seeking proofs and using verification to ensure the resulting solutions are logically sound, researchers report. The system solved dozens of previously open problems across several mathematical fields, suggesting that artificial intelligence (AI) could become a useful tool for automated mathematical discovery and research. “[The authors report] that even unsuccessful proof attempts by AI could help them understand the problems better and make progress on solving them,” write Jeremy Avigad and Matthew Ballard in a related Perspective. “This underscores that an essential goal of developing AI for mathematics is to support mathematicians in the search for knowledge and understanding that lead to further advances.” Large language models (LLMs) have demonstrated growing ability to solve difficult mathematical problems, but their tendency to produce subtle logical errors or “hallucinations” makes them unreliable for research without extensive human expert review. One promising way to mitigate these issues is to have AI agents generate mathematical proofs in formal programming languages such as Lean, which automatically verifies each logical step and prevents errors from going unnoticed. While this approach has been successfully applied to competition mathematics and in the human-aided formalization of natural language arguments, its potential in solving open research-level mathematical problems remains unknown.
To address this gap, George Tsoukalas and colleagues developed AlphaProof Nexus, a framework that uses multiple AI agents to search for mathematical proofs with feedback from the Lean compiler. Tsoukalas et al. also developed a more advanced, full-featured agent that coordinated subagents through an evolutionary algorithm to use AlphaProof as a specialized proof tool. In tests, the system was able to solve nine of the 353 attempted Erdős problems, including two that had remained unsolved for more than 50 years. It was also able to solve 44 of 492 open On-Line Encyclopedia of Integer Sequences (OEIS) conjectures as well as several other research-level problems in fields such as algebraic geometry, optimization, quantum optics, and graph theory.
Advancing mathematics research with AI-driven formal proof search
Article Publication Date
8-Oct-2026
How healthcare can benefit from AI, without costing the world
Artificial Intelligence is already widely used in hospitals and medical research. Can a new way of thinking unleash the technology’s green credentials?
Artificial Intelligence (AI) has had a transformative effect on healthcare. The technology has been tested and applied in almost every area, from disease diagnostics to AI-powered digital clinics.
The rationale always tracks back to efficiency: AI-technology will achieve more with less. In theory, greater efficiency contributes to sustainability.
But what about the environmental cost? Will healthcare be picking up the bill later down the line?
These are the questions being asked in a new paper, Green Artificial Intelligence in Health Applications.
Green AI
Environmental costs should be integrated into AI development, argues the paper’s co-author, Alok Mishra, Professor in Data Management and Software Engineering at NTNU.
“AI is coming up all around the world. It can’t be stopped,” admits Mishra. “AI models require lots of energy and huge data centres. These data centres consume large amounts of electricity and use significant quantities of fresh water.”
Mishra has previously proposed the need for ‘Green AI’; a holistic look at the technology’s impact on the environment.
His latest research examines the use of AI in health applications. It argues that the technology is “not working sustainably” and environmental consequence should be on equal footing with privacy, bias, fairness, transparency and other concerns about emergent AI-technology.
The environmental cost
Concerns about the environmental cost of AI are echoed by many. The International Energy Agency (IEA) estimates that data centres’ power consumption will double by 2030, reaching a level equivalent to Japan’s total electricity consumption.
Increased energy demand could lead to more carbon emissions and environmental degradation. This will affect quality of life and have health consequences for people around the world.
The IEA suggests, however, that AI can also be part of the solution. Fatih Birol, the agency’s Executive Director, spoke about “Energy for AI, and AI for Energy,” in the 2025 AI & Energy report. He points to the fact that AI could be used to operate power grids more efficiently, saving up to 175 gigawatts of transmission capacity in the process – enough to power Oslo for a year.
It is possible to develop AI sustainably. The technology can also be used for beneficial purposes. But unsustainable growth also points to a looming environmental cost.
The research asks the questions: What impact will this have on healthcare? And who will pay the price?
Healthcare an early adopter
Healthcare has been one of the technology’s most enthusiastic early adopters. Improvements in medical services and research have tangible benefits for people’s lives.
“These tools are very helpful for health professionals,” explains Mishra. “In no other area has the implementation of AI been as impactful as healthcare.
“For example, when doctors are dealing with thousands of pieces of information, they can use the technology to speed up analysis and assess the status of a particular patient or disease.”
Åsmund Flobak is an oncologist at the Cancer Clinic at St. Olav’s Hospital, professor at NTNU and senior research scientist at SINTEF. His field is among those that have adopted AI technology in healthcare.
“I’m involved in next-generation diagnostics for cancer patients, where we cultivate ‘living biopsies’ from patients to test drugs on the patients’ own cells,” explains Flobak. “Here we are using AI in image analysis to assess which of the cells are dying and which are not when exposed to different drugs.”
“In the Cancer Clinic we also routinely use AI-assisted drawing of what should be irradiated and what should be spared during cancer radiotherapy. We have started using auto-generated notes in patient consultations. AI will also soon come with tools to help us parse all data available for each patient,” says Flobak.
AI is increasingly used in a wide range of areas, including medical imaging, diagnostics, treatment planning, drug discovery, hospital management and telemedicine.
Flobak was asked whether, in his experience, environmental impact is considered when the technology is introduced?
“It is not something we discuss actively, no. This is something that should be sorted out at the policy level. The benefit to patients is difficult to turn down, for instance when using AI to ensure irradiation doses to healthy tissue are kept as low as possible.”
“Personally, I’m optimistic about our energy prospects. But these are political questions more than scientific or medical ones. In my daily life as a doctor, I prioritise every benefit I can give my patients, within the guidelines and regulations I work under.”
Environmental impact
When offered the opportunity to accelerate life-saving research, environmental impact has not always been prioritised in healthcare, although sometimes it is considered.
Mishra’s research systematically reviewed 47 studies of AI in healthcare, where sustainability was a consideration. They found the results to be ‘siloed’ – well-intentioned initiatives, which did not always take the bigger picture into account.
The concept of Green AI is that AI applications cannot solely be implemented in a sustainable manner or, say, built on efficient models. It is not enough to simply be hosted by energy-optimised data centres or rely on the fact the technology will be used for good.
In order be truly ‘green’, AI development must take all aspects of its environmental impact into consideration.
This requires a life-cycle assessment, considering everything from manufacture to usage to recycling at the end of a product’s life. Mishra compares it to a kitchen appliance which has an energy rating, or an airline providing passengers with information about carbon emissions, and offering the chance to offset these through a donation.
It’s a tall ask for an industry which is typically shrouded in secrecy and not forthcoming about its energy use and data storage, acknowledges the professor.
A paradigm shift
Mishra argues that a paradigm shift is necessary in order to address the environmental, ethical and operational challenges of AI.
“It is not just a political question anymore. Stakeholders and citizens are facing environmental consequences in daily life,” stresses the researcher.
He points to the environmental disasters which have hit parts of Asia and Europe this year.
“Landslides, melting glaciers, flash floods and heatwaves put pressure on health systems,” says Mishra. “Environmental consciousness therefore has to be at the core of AI development and application in healthcare.”
“AI use and its applications should be part of the picture, but they should also take into consideration sustainability issues. Is the answer to AI simply more AI? No, as researchers we want AI to be used in a sustainable manner so that it can provide more benefits to society.”
High-precision Global Navigation Satellite System (GNSS) positioning depends on successful carrier-phase ambiguity resolution, but this remains difficult in urban canyons, dense vegetation and other challenging environments. This study introduces a residual-based machine learning (ML) validator that uses features less sensitive to environmental degradation and a compact Multilayer Perceptron (MLP) classifier. Tested on real-world datasets from an Unmanned Ground Vehicle (UGV) and an Intelligent Passenger Car (CAR), the method improves correct ambiguity fixing while sharply reducing wrong fixes. It achieves classification accuracy and precision above 90% on independent tests and supports real-time use, offering a practical path to more reliable high-precision positioning.
Conventional GNSS ambiguity validation often works well in open skies. In challenging environments, however, non-line-of-sight (NLOS) reception, multipath and signal blockage create model-reality mismatches. Model-driven tests such as the R-ratio test and the Fixed Failure-Rate Ratio Test (FFRT) rely on specific assumptions about the underlying GNSS model, and their performance can deteriorate when these assumptions are violated, leading to many wrong or missed fixes Machine learning can capture nonlinear relationships, but earlier models were often trained on benign datasets, depended on conventional statistical indicators, and required substantial computation and memory. These limits have hindered deployment on resource-constrained platforms and in real-time high-precision positioning. Given these challenges, there is a need for in-depth research on lightweight, generalizable and residual-aware validation for GNSS ambiguity resolution.
Researchers from the School of Geodesy and Geomatics at Wuhan University, the Chinese Antarctic Center of Surveying and Mapping, the University of Electronic Science and Technology of China and Baidu Online Network Technology published (DOI: 10.1186/s43020-026-00216-w) the study on 30 September 2026 in Satellite Navigation. The paper presents a residual-based machine learning validator for GNSS ambiguity resolution in challenging environments. It combines residual-based features with a compact Multilayer Perceptron to decide whether a fixed integer ambiguity solution should be accepted.
The validator extracts three key residual-based features: Ambiguity Difference Root Mean Square (ADR), Phase Residuals Root Mean Square (PRR), and Phase Consistency Root Mean Square (PCR). PRR measures post-fit carrier-phase residuals, while PCR checks consistency between frequencies after ambiguities are fixed. In feature-importance tests, PRR and PCR were the most influential, with stronger correlations to wrong/correct labels than conventional indicators. The classifier is a single-hidden-layer MLP with only 16 hidden neurons, a model size of about 2.8 KiB, and an inference time of 28 ms for more than 350,000 samples. On a 260-hour UGV dataset from Suzhou and a 240-km car dataset from Wuhan, it achieved accuracy and precision above 90%. In UGV tests, the average correct fixing rate reached 85.21%, versus 77.26% for FFRT, while the wrong fixing rate fell to 1.42% from 16.37%. In the CAR-S5 urban scenario, the correct fixing rate was 85.15%, an improvement of 10.55% over FFRT, with a wrong fixing rate of 0.92%. In addition, the proposed method requires an average of only 1.244 ms per epoch for ambiguity resolution, compared with more than 5 ms for the other methods. On the public SmartPNT-POS dataset, it reached a 72.40% correct fixing rate and a 4.50% wrong fixing rate, outperforming POSM and FlexRTK.
The authors said the key advance is not simply adding machine learning, but giving it residual-based evidence that remains informative when conventional statistical assumptions break down. They said the most influential features were PRR and PCR, which directly test whether the fixed ambiguities are consistent with the carrier-phase observations. They said the compact MLP was chosen deliberately, because real-time GNSS users need low latency and small memory footprints. They added that the method reduces both missed and wrong fixes, although performance may still degrade under extremely weak observation models or severely biased float solutions.
The validator is designed for real-time, high-precision positioning on platforms with limited computing resources, including autonomous vehicles, unmanned ground vehicles, smart agriculture equipment and other location-based services. By improving ambiguity fixing in urban canyons, dense vegetation and other challenging environments, it could help maintain centimeter-to-decimeter positioning continuity where conventional methods frequently fall back to float solutions or output dangerous wrong fixes. The authors suggest the approach can be extended to Precise Point Positioning with ambiguity resolution (PPP-AR) and PPP-Real-Time Kinematic (PPP-RTK). Future work will add environmental features and exploit the temporal invariance of ambiguities to improve robustness across more diverse conditions. Such advances could support safer navigation and more reliable geodetic, surveying and mapping applications.
This work was supported in part by the National Science Fund for Distinguished Young Scholars of China (Grant No. 42425003), in part by the Shenzhen Science and Technology Program (Grant Nos. CJGJZD20240729143002004), in part by the Shanxi Provincial Key Research and Development Program (Grant No. 202502010102024), in part by the National Natural Science Foundation of China (Grant Nos. 42274034), and in part by the Special Fund of Wuhan University-Baidu Map Beidou Cooperative High-Precision Positioning Technology Joint Laboratory.
Satellite Navigation (ISSN: 2662-1363; ISSN: 2662-9291) Satellite Navigation is the official journal of the Aerospace Information Research Institute. The journal aims to report innovative ideas, new results, and progress in the theories, techniques, and applications of satellite navigation. The journal welcomes original articles, reviews and commentaries.